ArXiv Is Cracking Down on AI-Generated Research Papers and Manufactured Citations

arXiv is a curated research-sharing platform that promotes scientific innovation and equitable access to scholarship worldwide. Since its founding in 1991, arXiv has been freely available and open to all. arXiv now hosts over 2.9 million scholarly articles across eight subject areas.

As a pioneer in digital open access, arXiv.org is tightening its submission rules around AI-generated papers and fabricated citations is one of the clearest signs yet that generative AI is beginning to stress-test the foundations of scientific publishing. As language models become more capable at producing convincing academic writing, the line between legitimate research assistance and fully synthetic misinformation is getting harder to detect.

The bigger issue is not just fake citations — it is scale. AI can now generate enormous volumes of plausible technical content faster than human reviewers can verify it. That creates a new credibility problem for academia, especially in fast-moving fields like machine learning and biotech where preprint culture already moves at extreme speed. The next phase of scientific publishing may depend less on producing information and more on proving authenticity, sourcing, and human accountability.
READ ARTICLE

A realistic look at how AI could dramatically improve life, industry, and human potential

Getty Images / Unsplash

Big Think’s The Great Progression explores a future where artificial intelligence, robotics, biotech, and automation converge into a single accelerating force that could redefine everyday life by 2050. Rather than framing AI as just another software wave, the article argues we are entering a period of civilizational-scale transition where machines increasingly handle cognition, labor, transportation, manufacturing, and even scientific discovery.

What makes the piece compelling is that it treats AI less as a standalone technology and more as infrastructure for an entirely new economic era. Some predictions may lean optimistic, but the broader direction feels increasingly difficult to ignore. Frontier models are already compressing timelines across robotics and research, and the next decade may determine whether AI becomes a productivity revolution, a massive labor disruption, or both at the same time.

READ ARTICLE

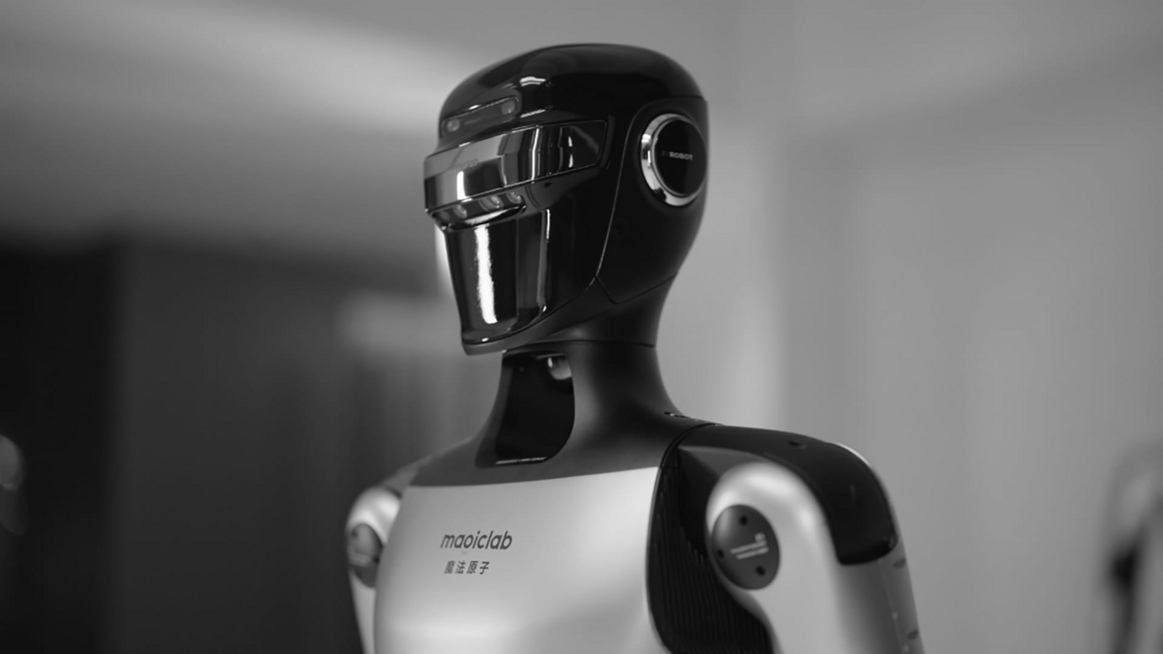
Synthetic Data May Be the Missing Scaling Layer for General-Purpose Robots

Photo: console.kr-asia.com

MagicLab’s latest push into synthetic data and robot world models highlights a growing reality inside embodied AI: collecting enough real-world robotics data is becoming economically impossible at scale. The company’s new Magic-Mix system combines a world model with a synthetic data engine designed to continuously generate training environments, feedback loops, and robotic interaction data without relying entirely on physical deployments.

The broader implication is significant. Frontier robotics companies are increasingly treating simulation the way large language model companies treated internet text datasets a few years ago — as the raw fuel for scaling intelligence. If synthetic environments become realistic enough, the competitive advantage may shift from who owns the most robots to who can generate the best virtual worlds for training them. That could dramatically accelerate humanoid robotics, dexterous manipulation, and autonomous systems over the next several years.

READ ARTICLE